Selected work · 14
Jupiter
A reproducible search-and-review workflow for faint lightning candidates in Cassini ISS imagery.
Explore the engineering ↓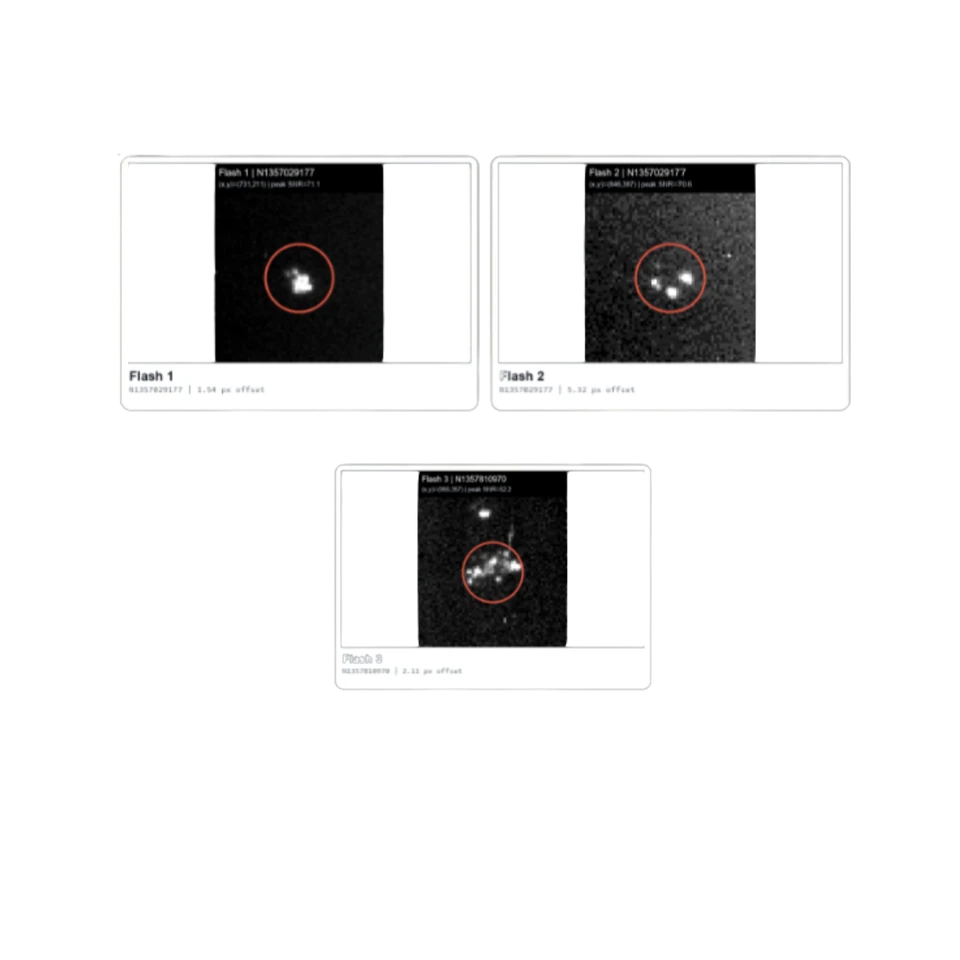
- My role
- Classical detector · filtering/ranking · review workflow
- Status
- Six published marks recovered · new events unconfirmed
- Focus
- Scientific imaging · computer vision · validation
Result & scope
The recorded run processes 221 images across nine date windows. All six published validation marks are recovered within 8 px; 106 prioritized review rows remain a review queue, not discoveries.
- 01
Detect
Normalize calibrated arrays and subtract a smooth background.
- 02
Filter
Measure connected bright regions and flag likely artifacts.
- 03
Rank
Link nearby detections and prioritize scientific review.
- 04
Review
Compare known marks and retain human label decisions.
Evidence from the project
Inside the work.
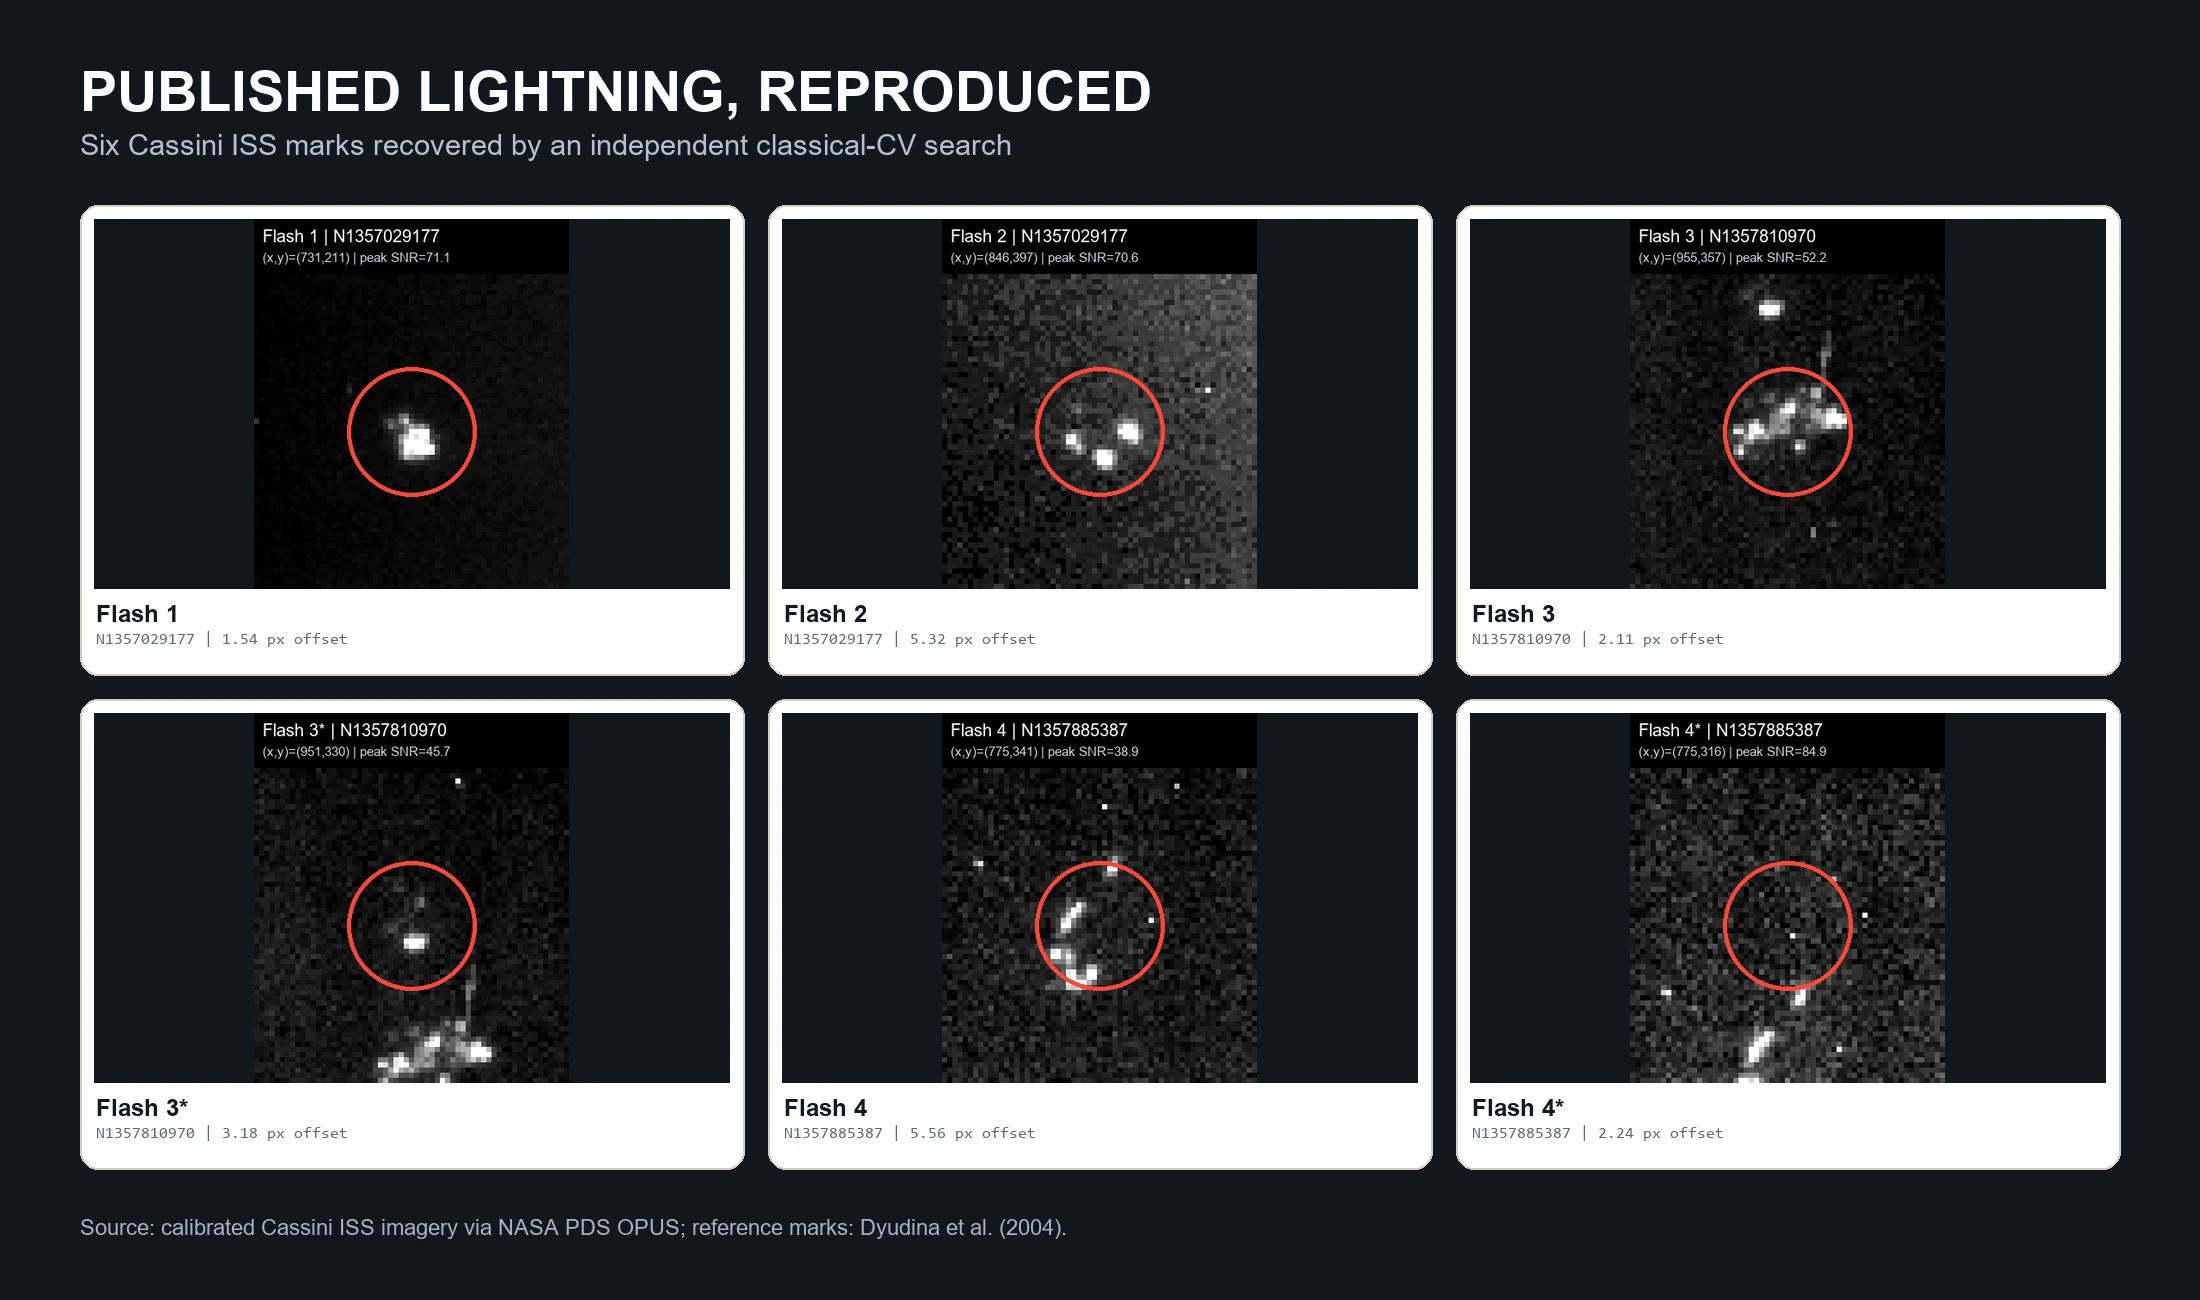
Published validation crops with marks; the reference set tests known-event recovery.
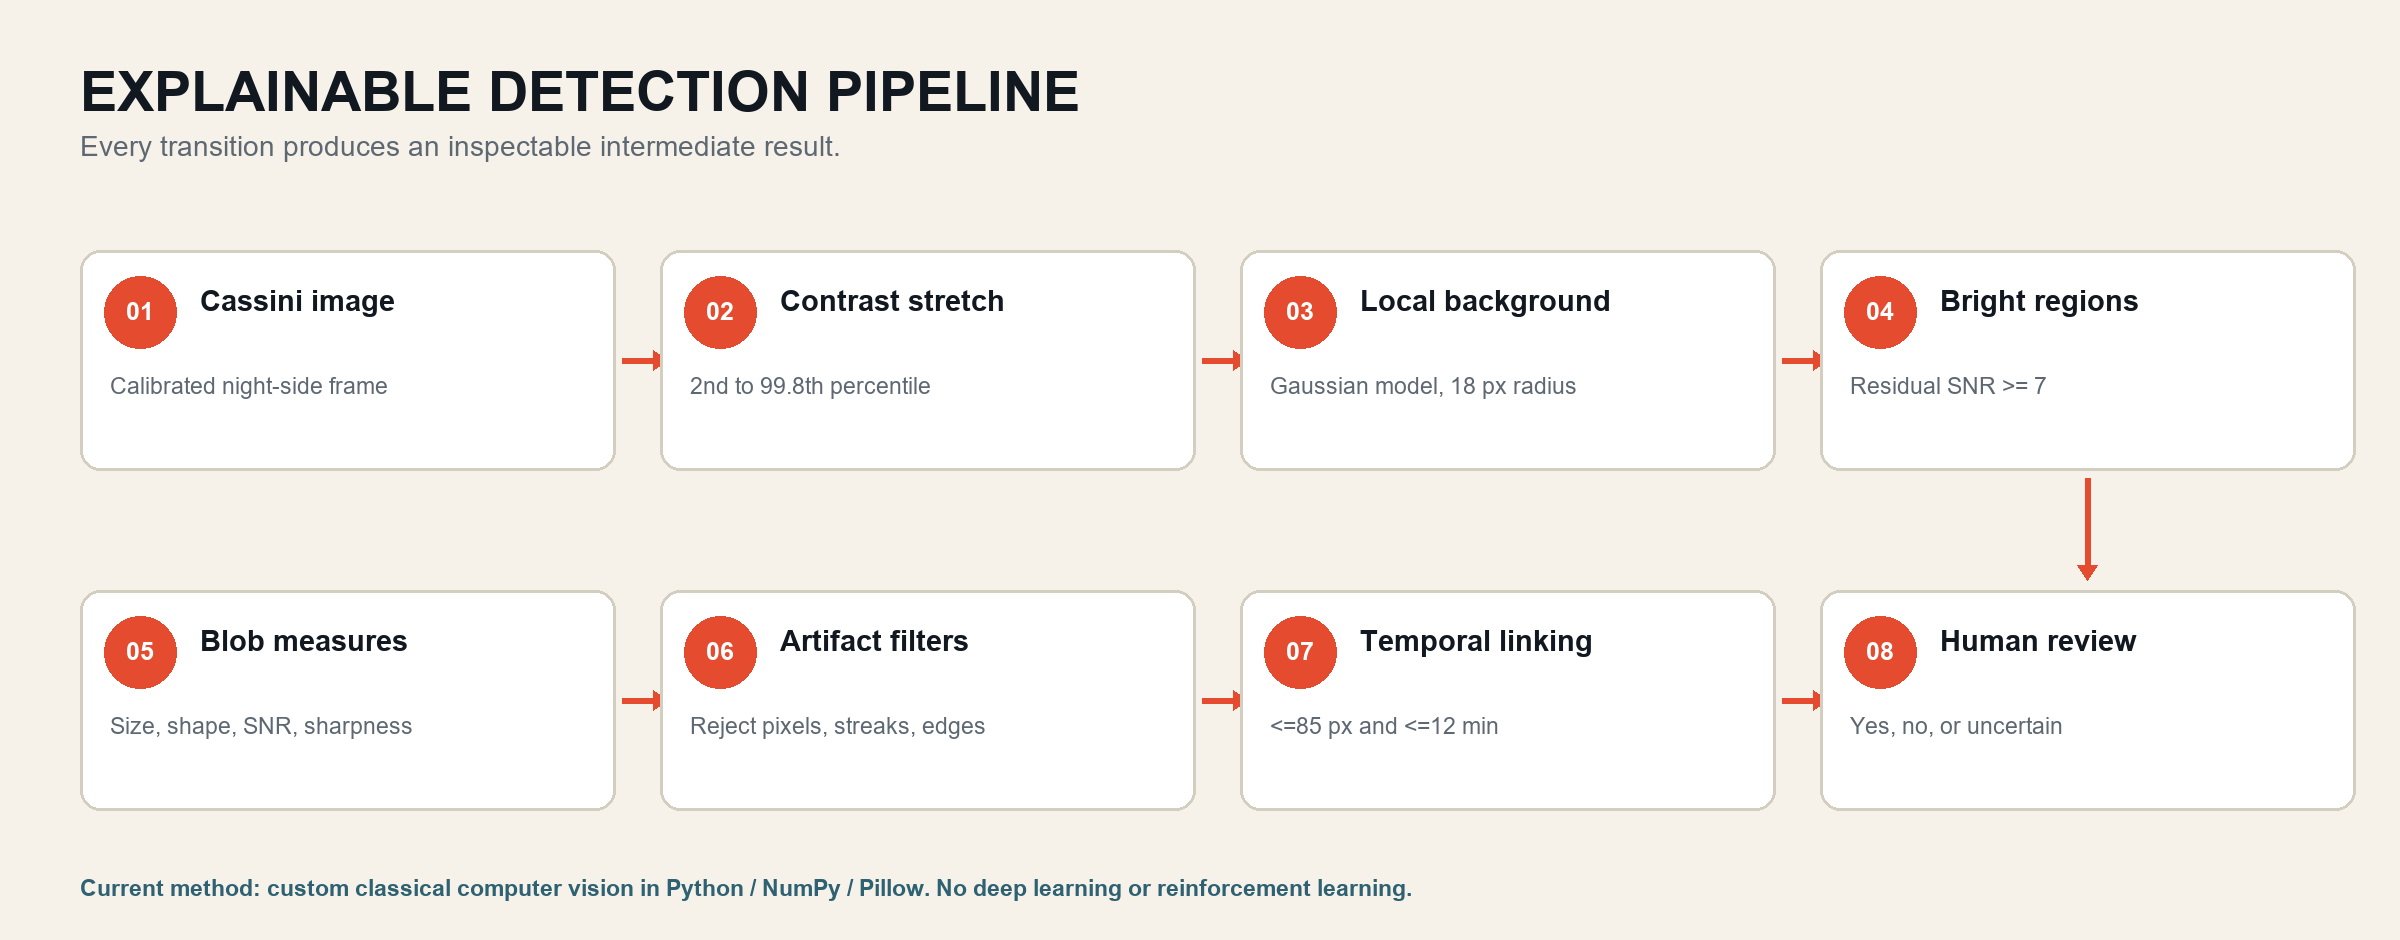
The implemented method is image processing and region analysis, not a trained neural detector.
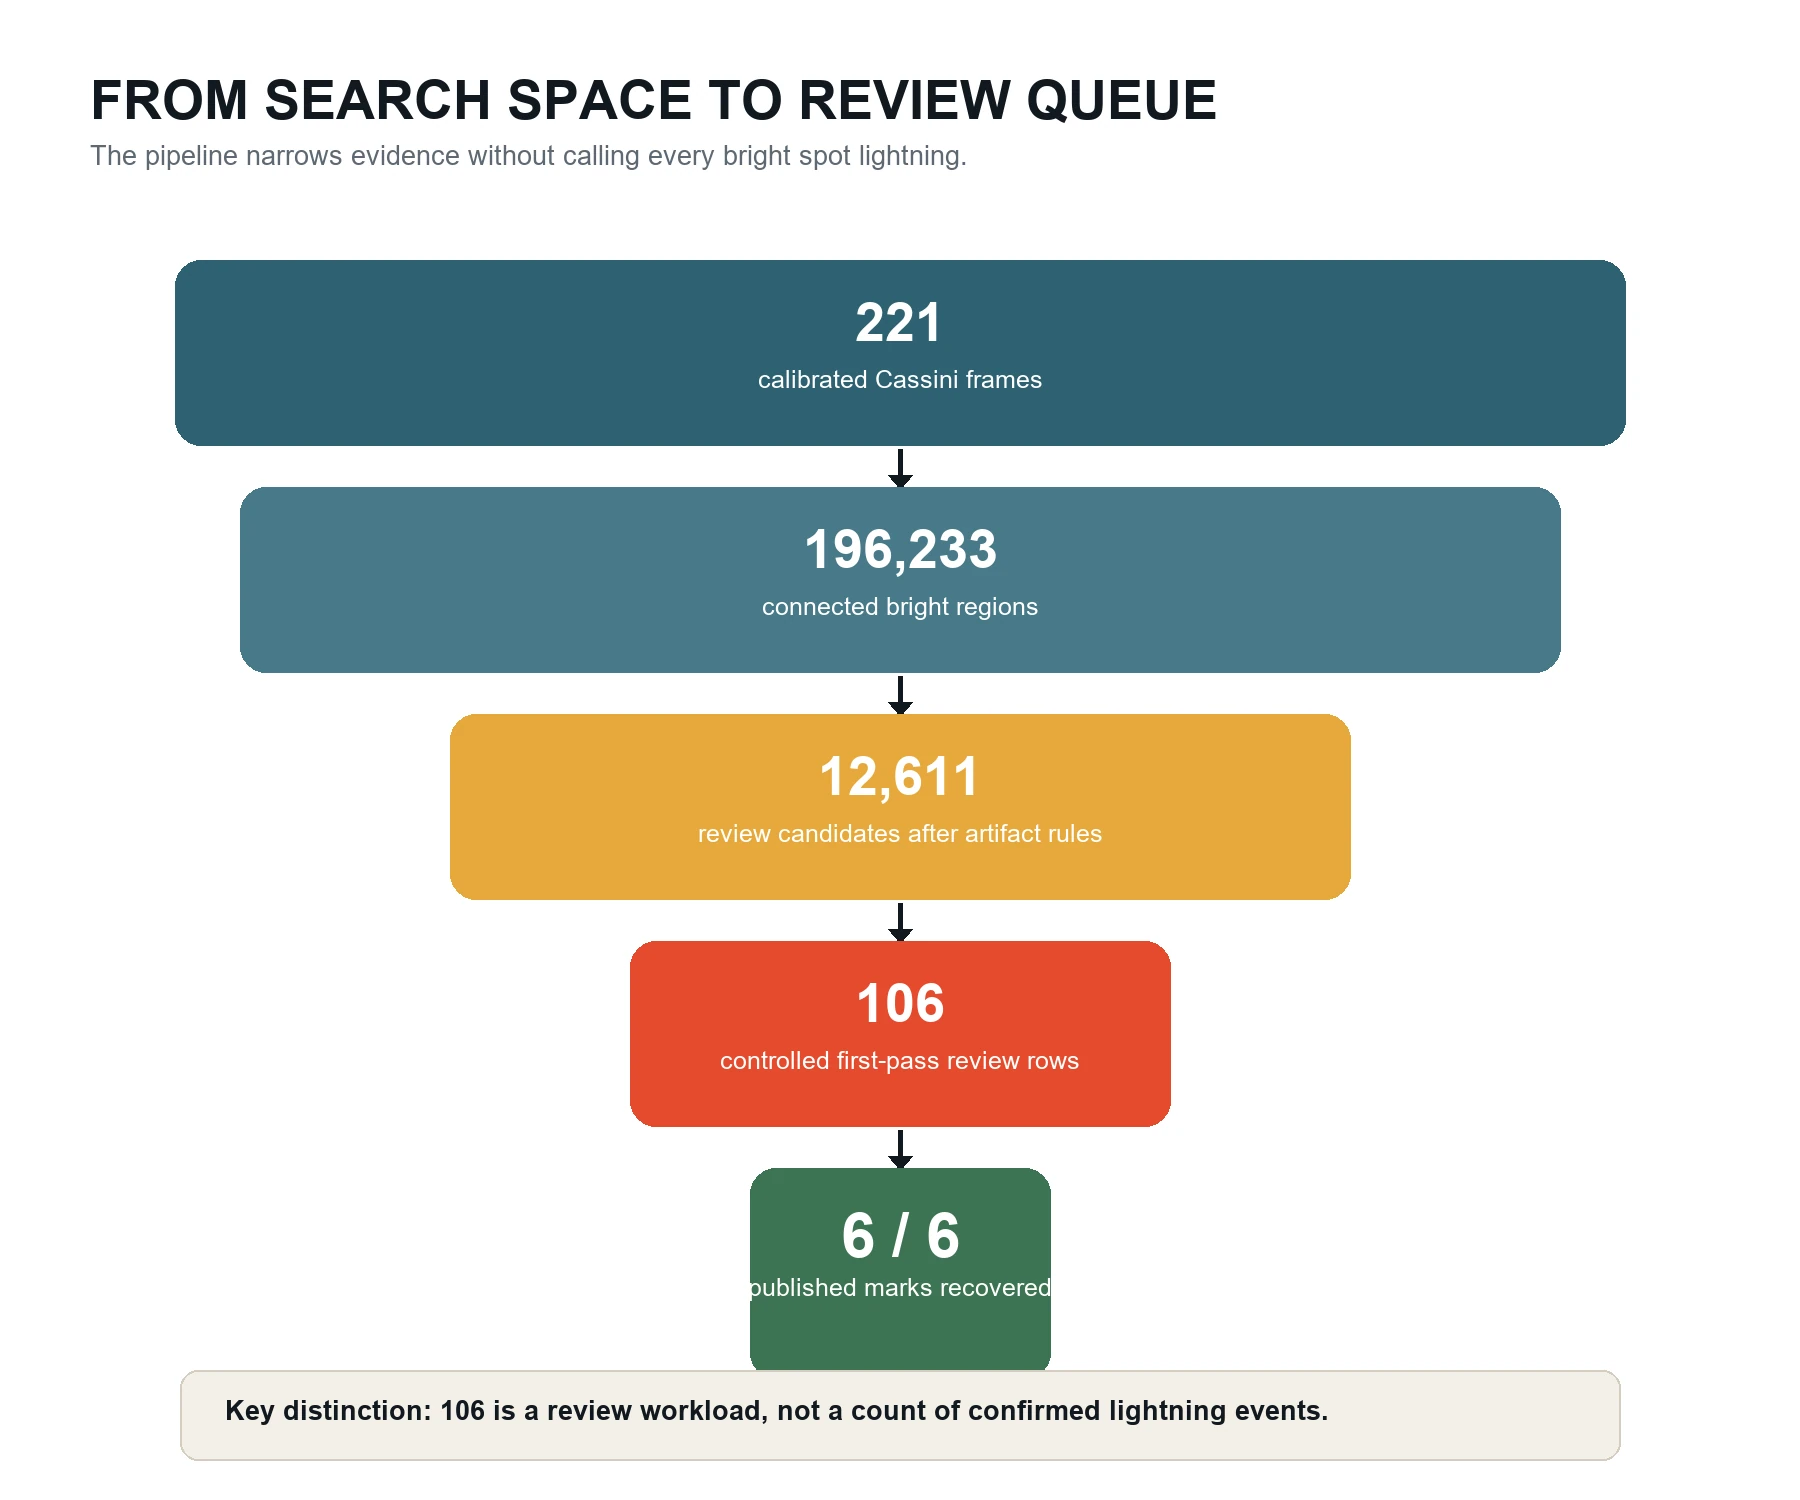
Raw regions, filtered candidates, and review rows measure different stages.
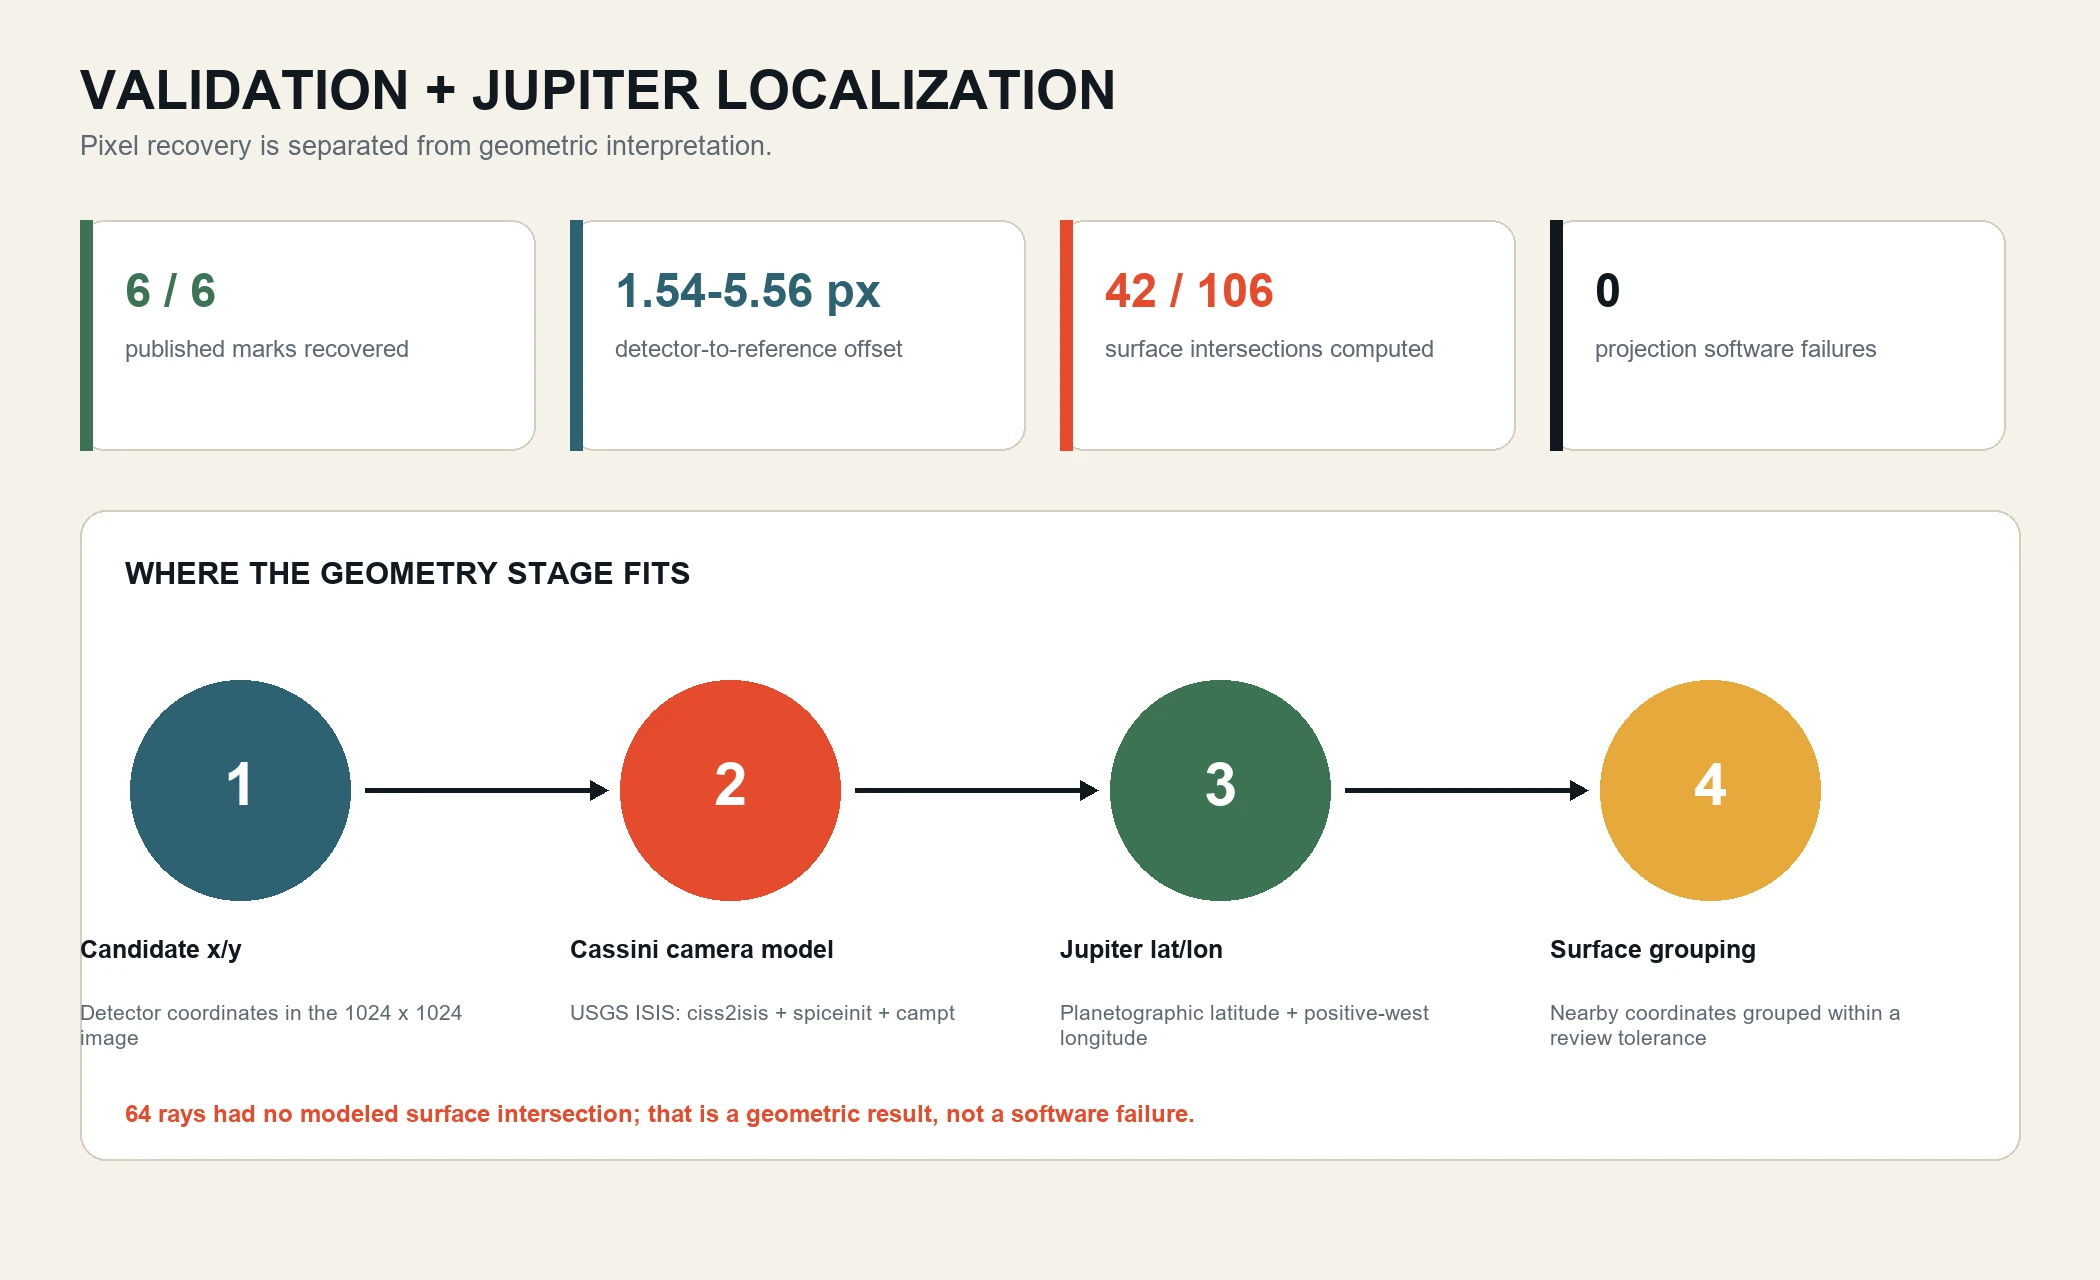
Localization checks and geometry work constrain the scientific interpretation.
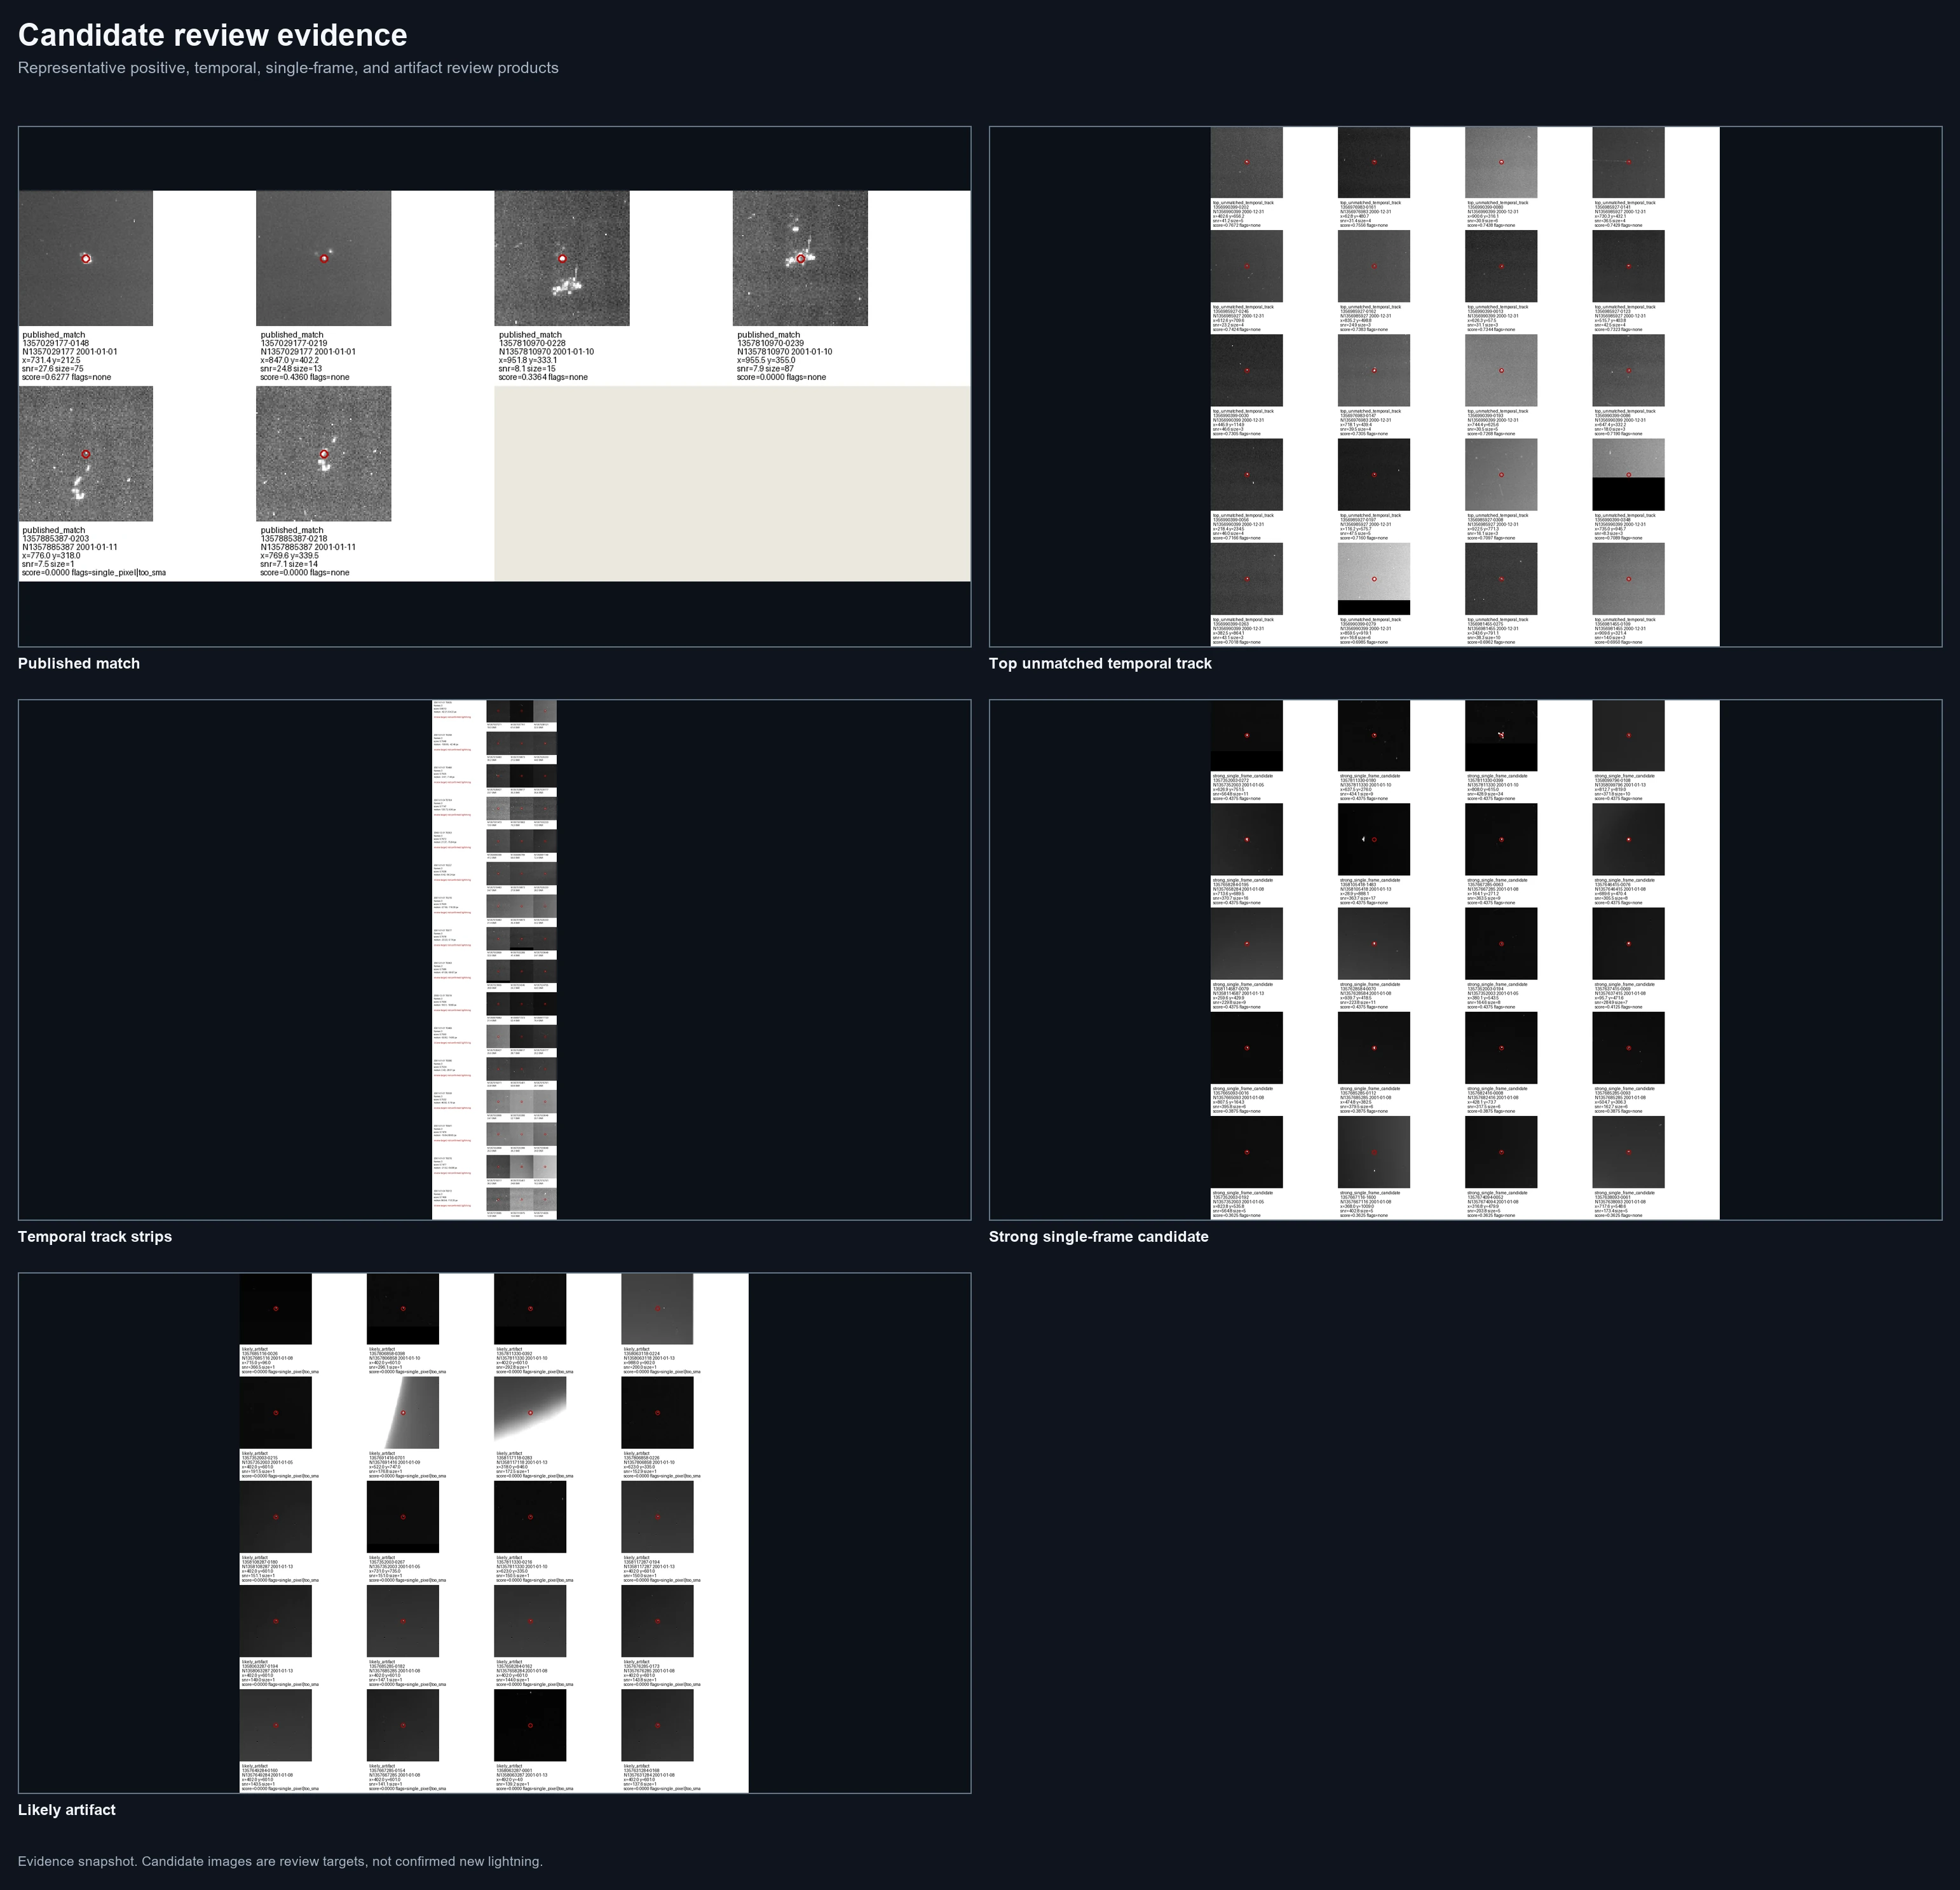
Unmatched candidates and artifacts are retained for inspection; none is promoted to a discovery here.
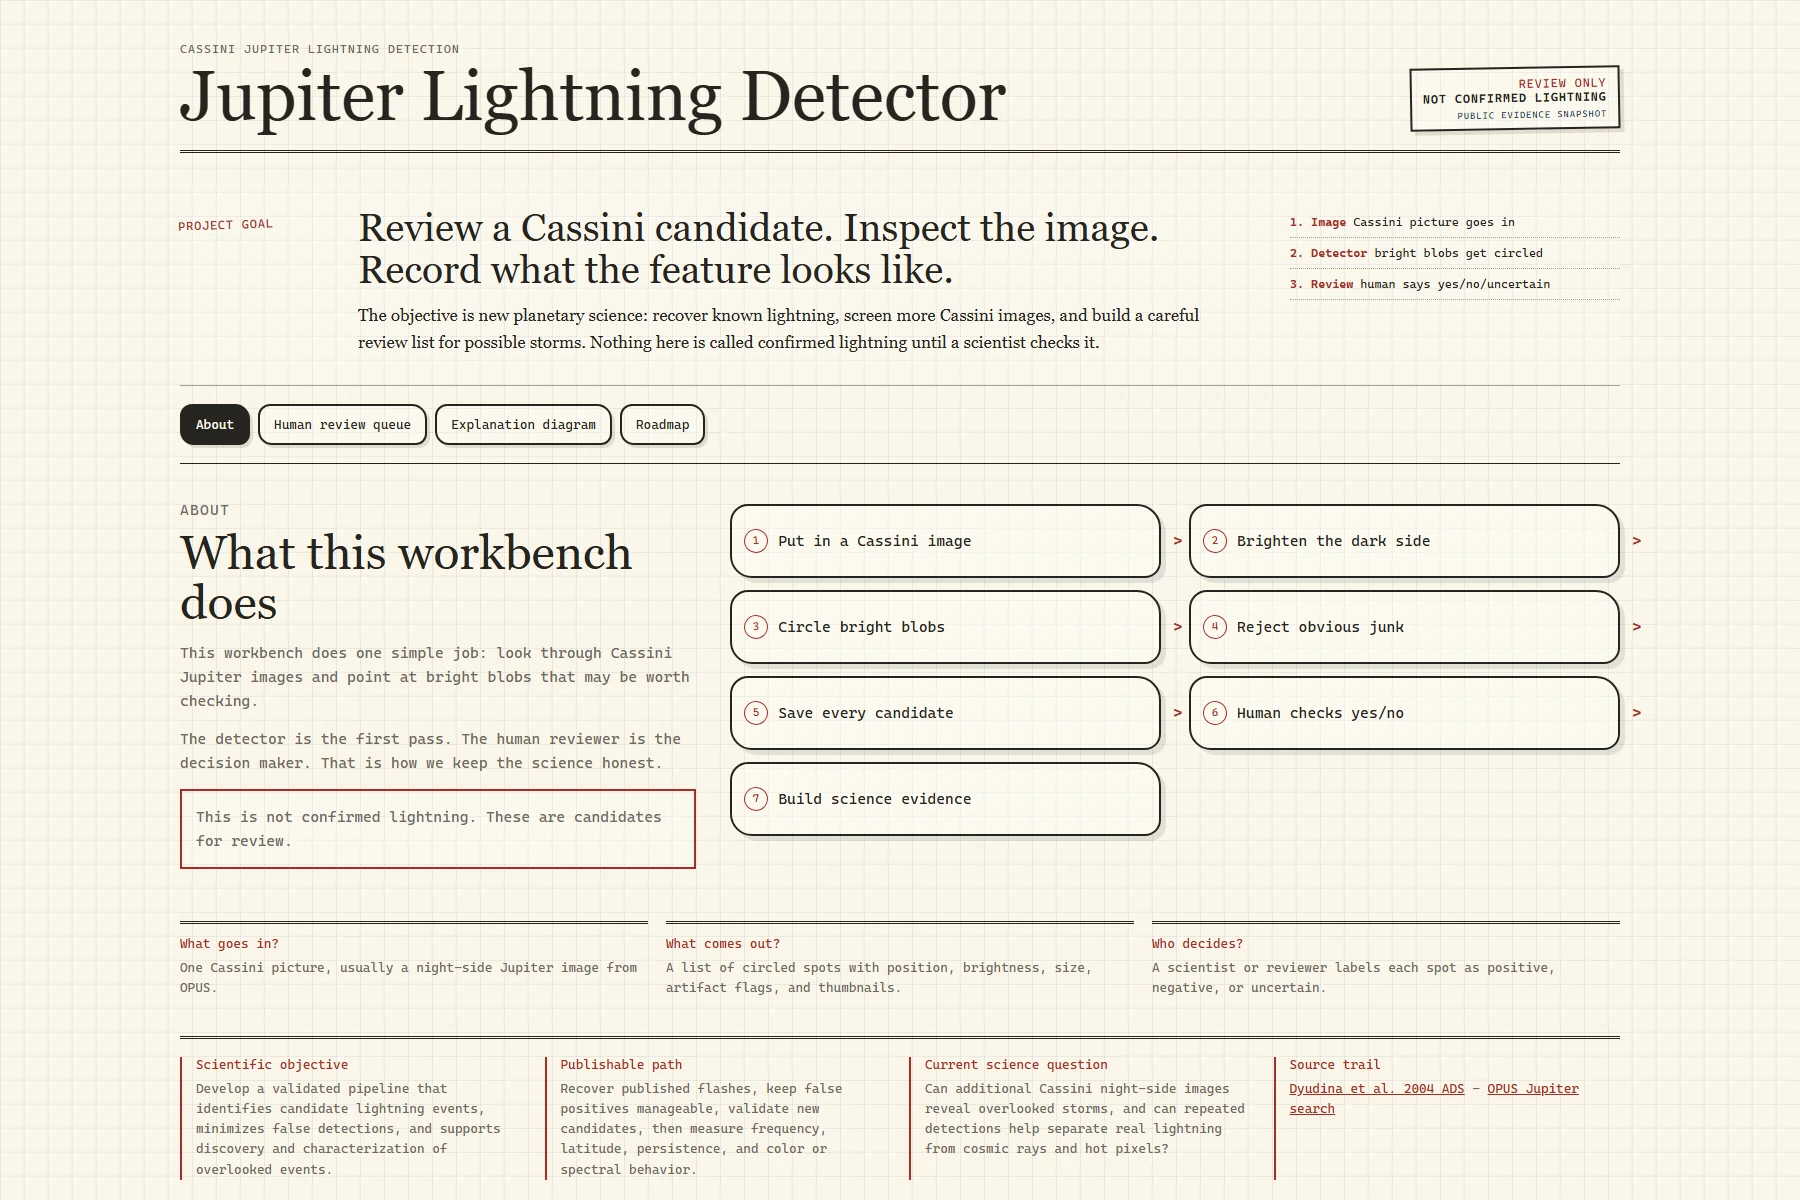
A workbench for traceable decisions. The supplied training-readiness snapshot has no accepted labels.
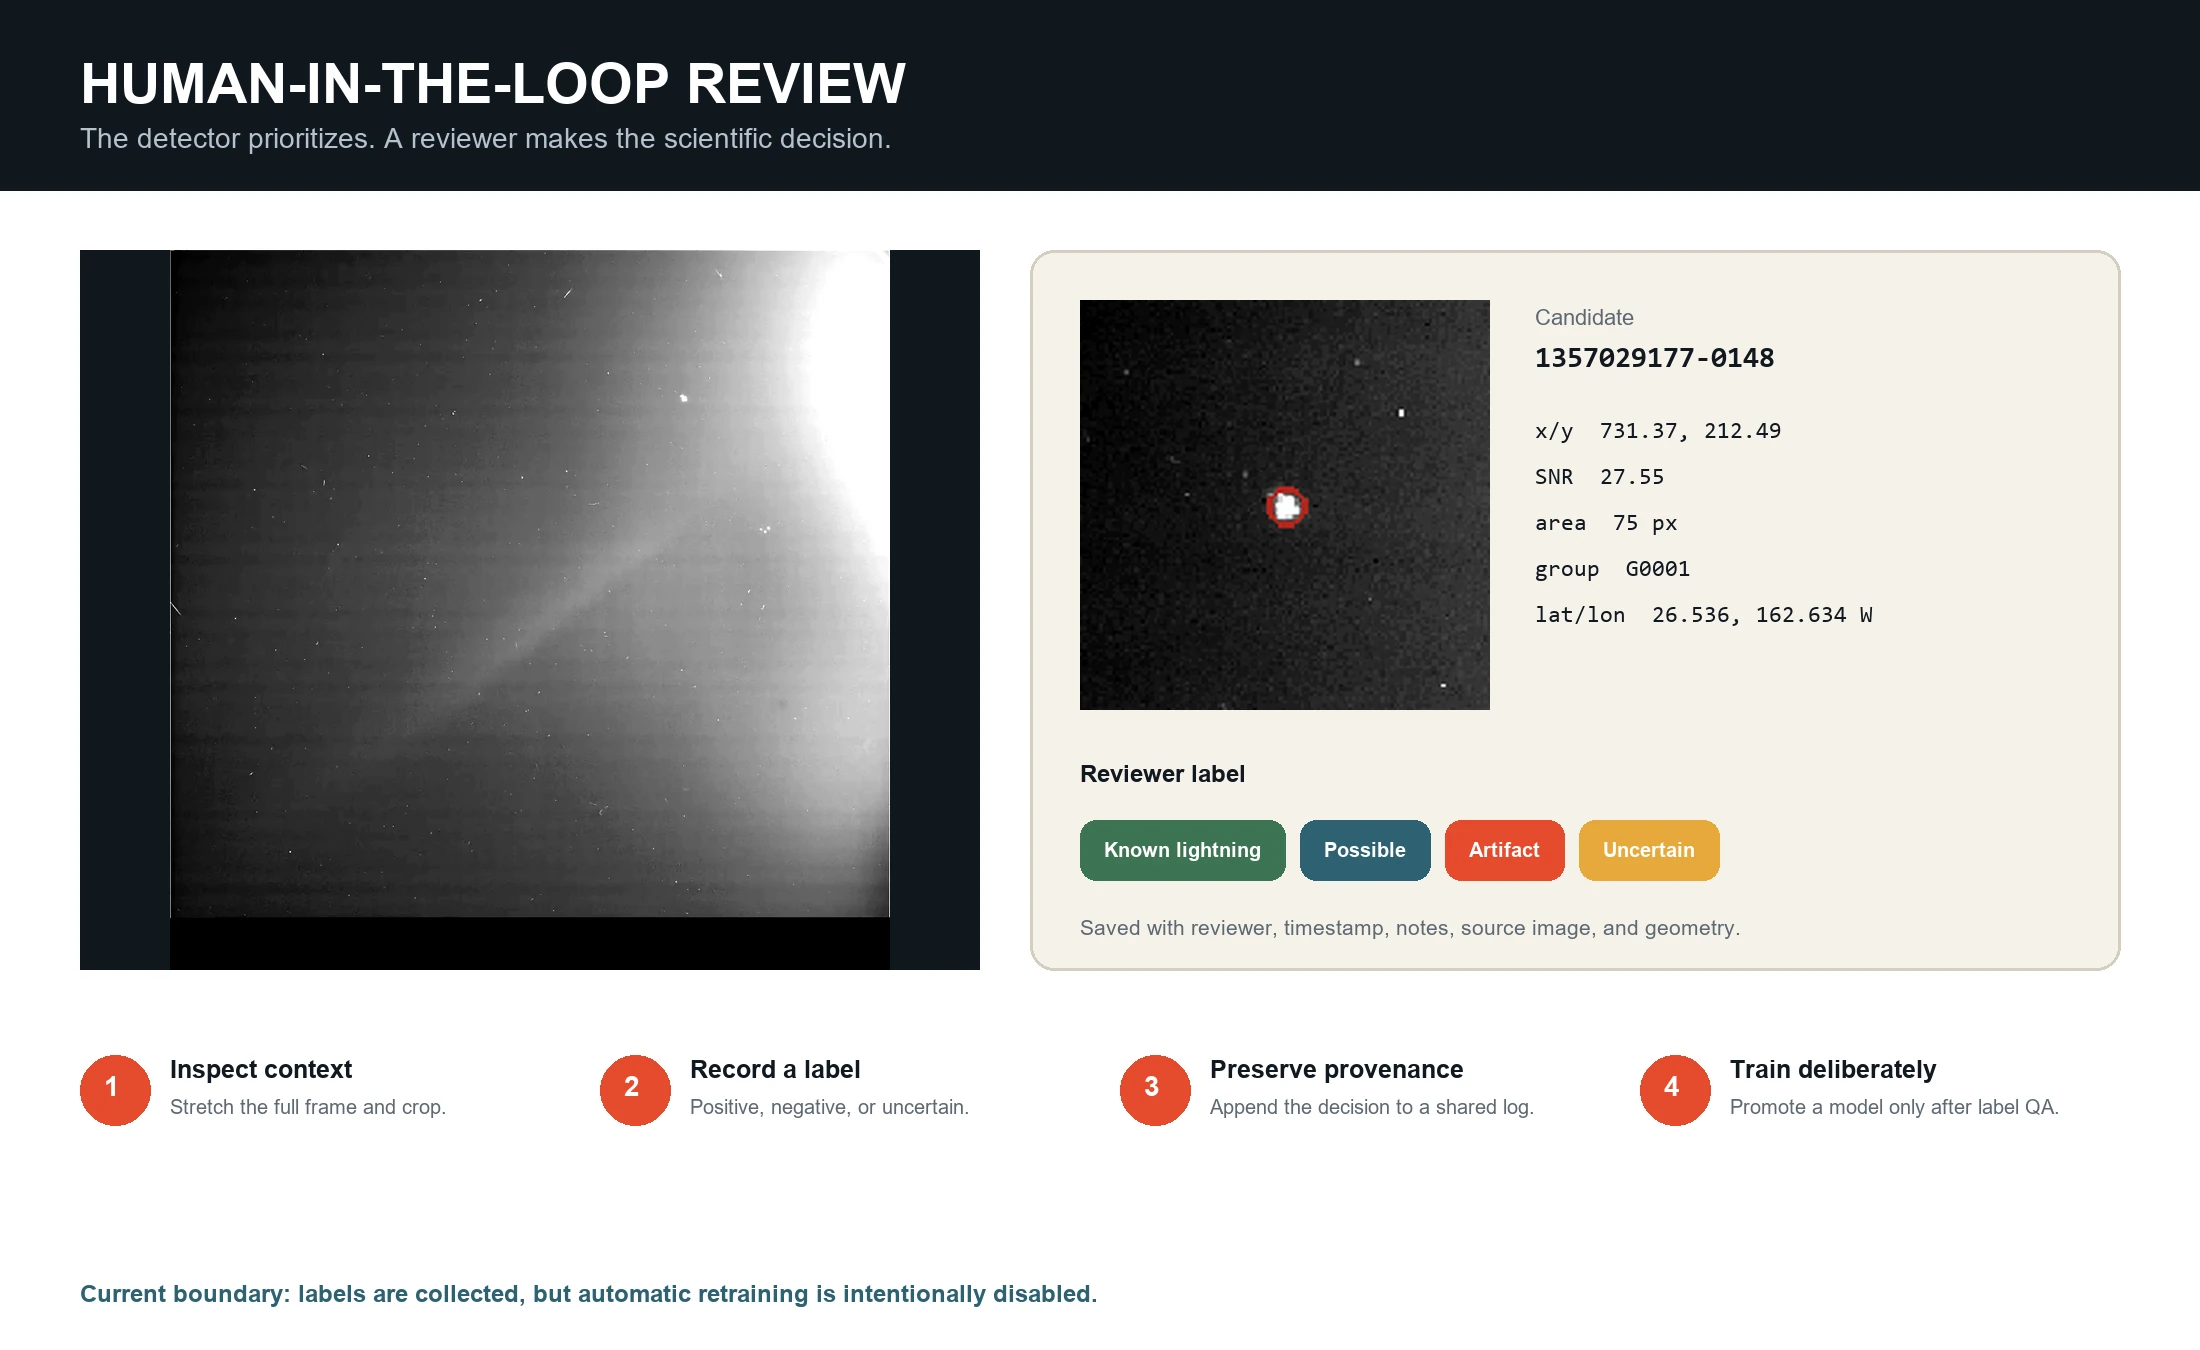
Labels and a frozen benchmark are prerequisites for a learned-model comparison.
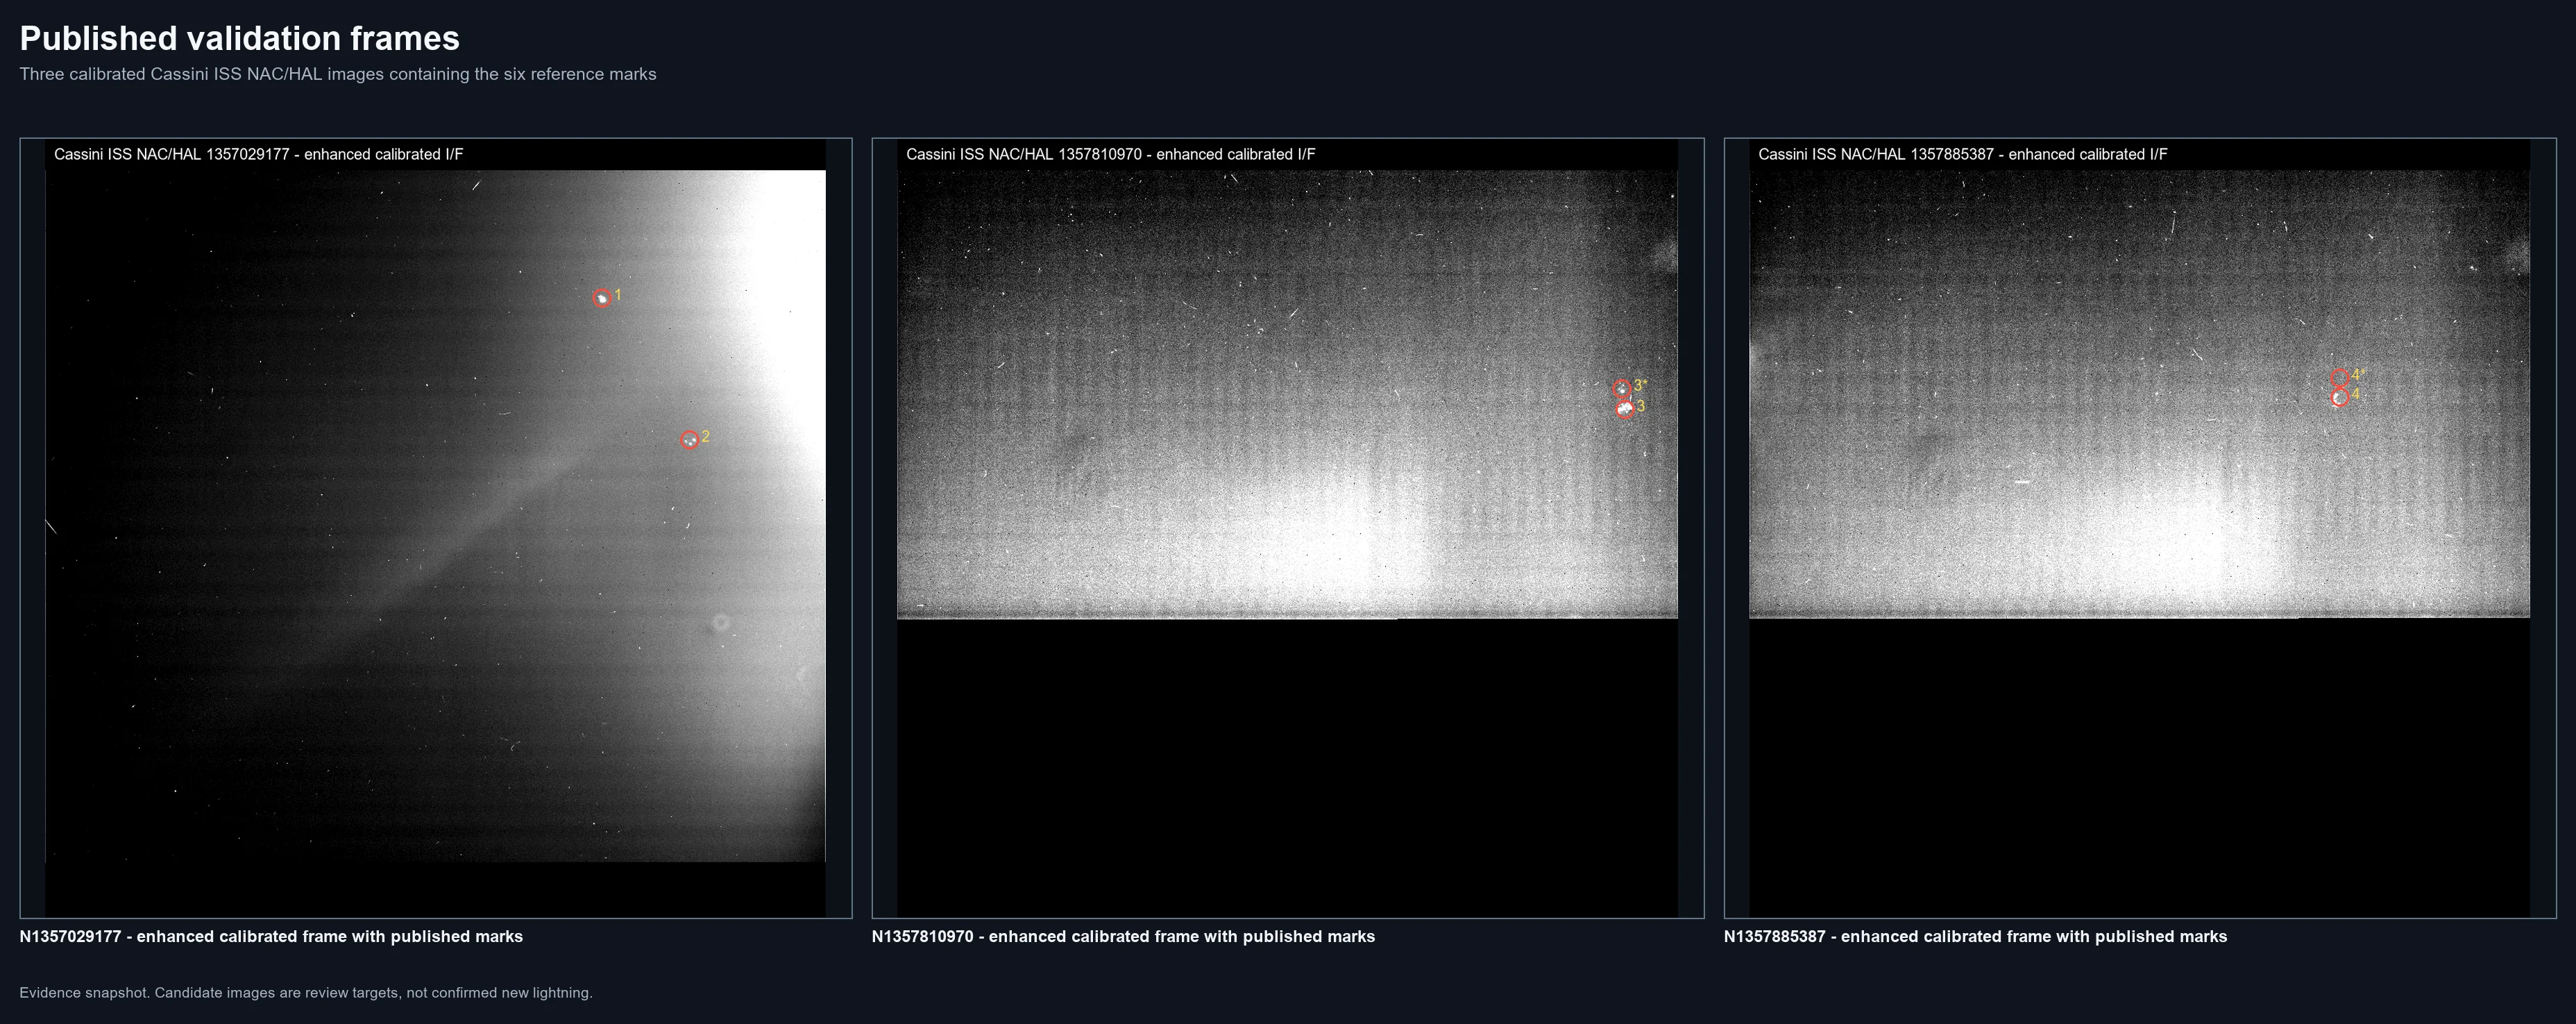
Full-frame context shows where the six published validation marks occur.
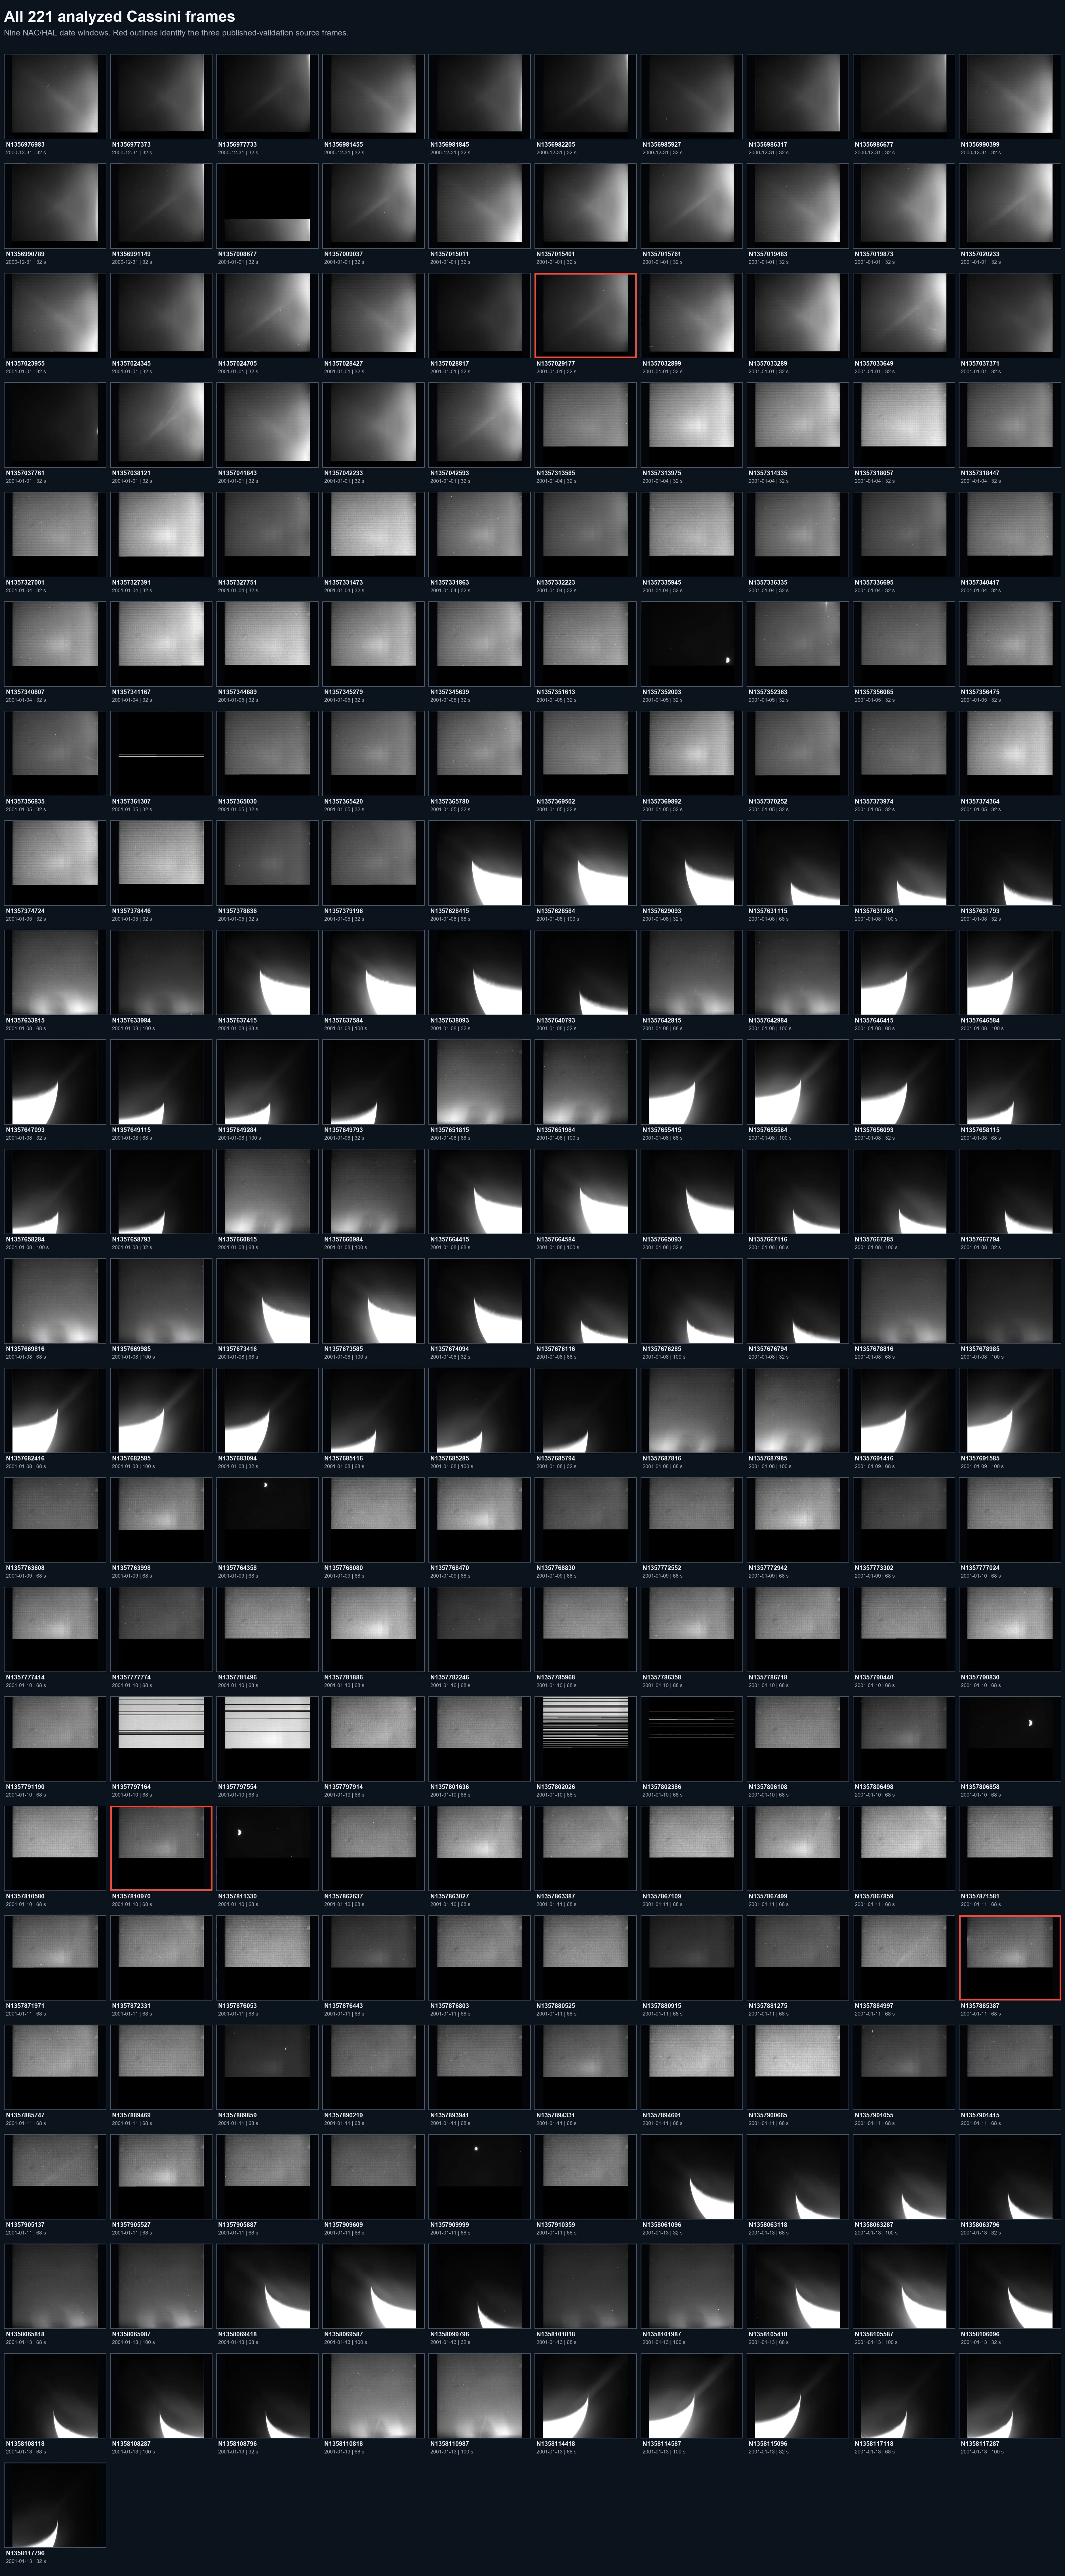
The montage documents the complete analyzed image corpus rather than only selected candidates.
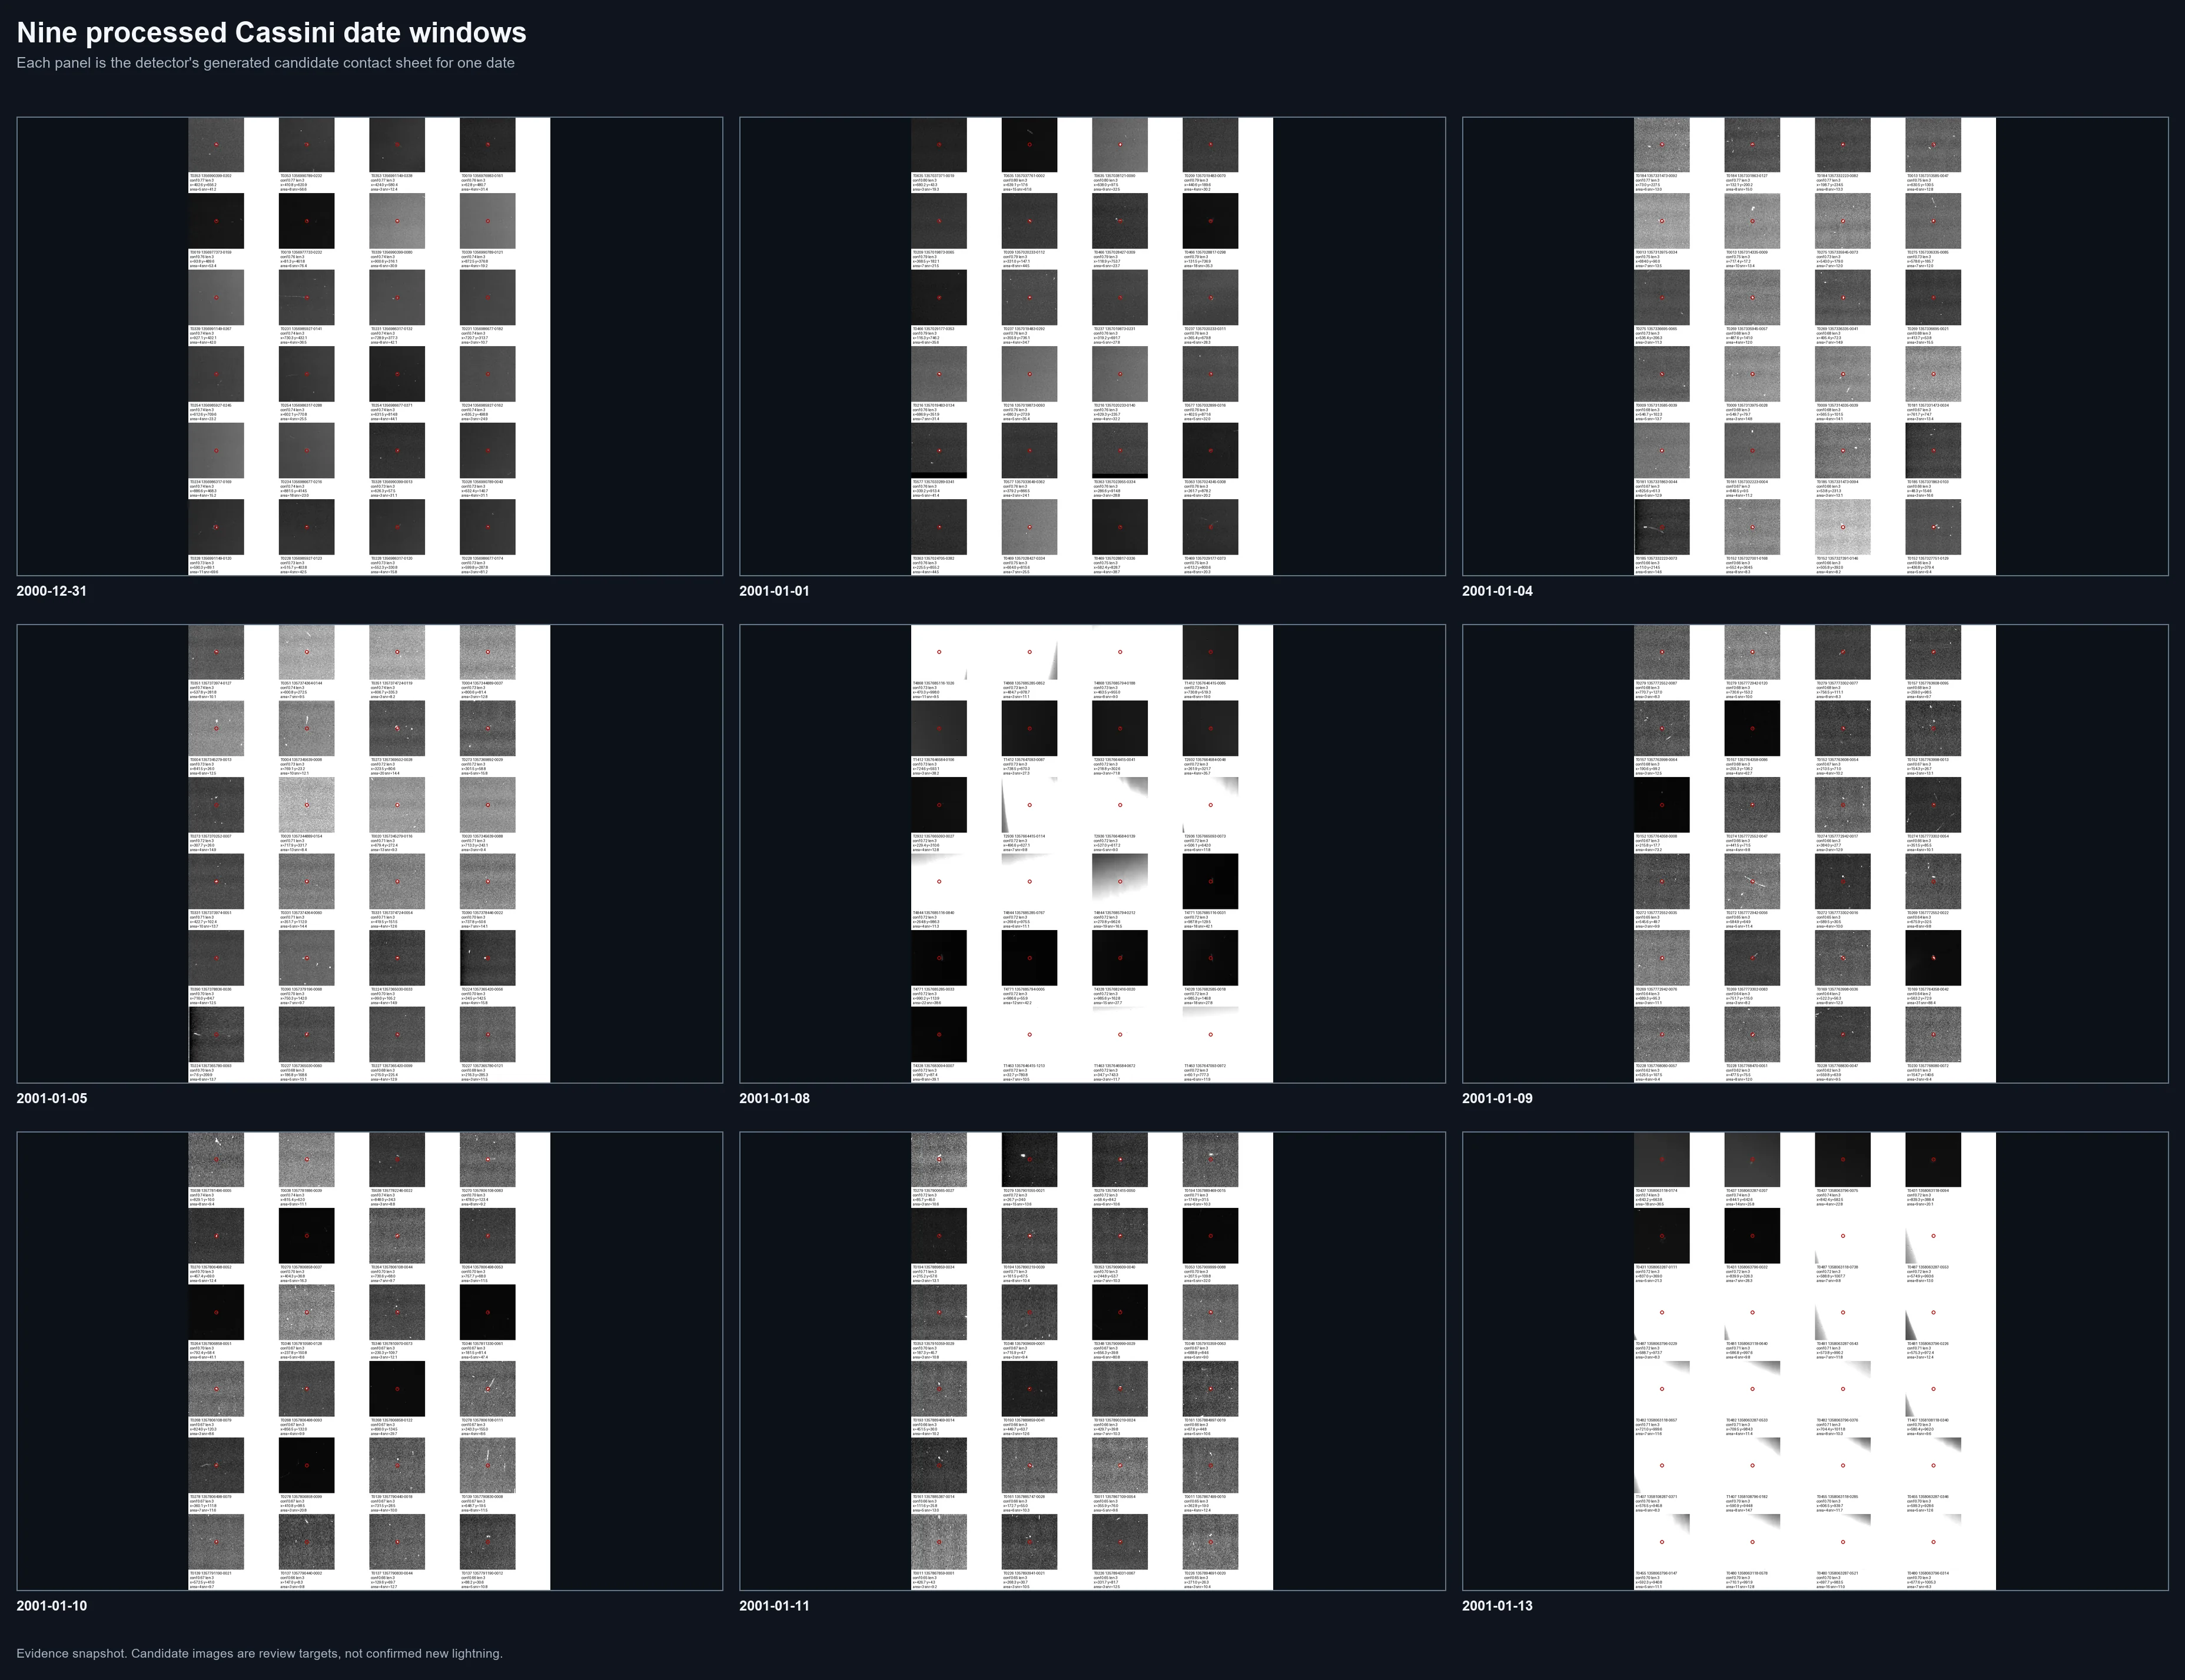
Date-grouped contact sheets expose the volume and variety passed to review.
| Stage | Count | Meaning |
|---|---|---|
| Calibrated images | 221 | Nine date windows |
| Bright regions | 196,233 | Broad first-pass detections |
| Filtered candidates | 12,611 | Passed artifact filters |
| Prioritized rows | 106 | Human review packet |
| Known marks recovered | 6 / 6 | Within 8 px; not overall accuracy |
Implemented algorithm
The recorded implementation uses Python, NumPy, and Pillow on calibrated Cassini ISS image arrays. It normalizes the 2nd–99.8th percentile range, subtracts a Gaussian background with radius 18, and estimates noise as 1.4826 × MAD.
Pixels at SNR ≥ 7 form eight-connected regions. The detector measures centroid, area, peak/mean/integrated SNR, sharpness, and elongation. Review candidates require area ≥ 3, peak SNR ≥ 8, and no artifact flags.
Filtering and ranking are different stages
The snapshot contains 196,233 raw bright regions, 12,611 candidates after artifact filtering, and 106 prioritized review rows. A candidate can still be an artifact after passing a first-stage filter.
Temporal association uses an 85 px / 12 minute window. Ranking combines persistence, motion, diffuse structure, SNR, and an artifact penalty. Its score orders review work; it is not a calibrated probability that an event is lightning.
Validation against published marks
All six known marks are recovered within the recorded 8 px radius, with nearest-candidate offsets from 1.54 to 5.56 px. This is a useful recovery check on a small reference set, not a full precision/recall estimate over all 221 images.
Human review and scientific limits
The workbench and manifests separate published matches, unmatched tracks, single-frame candidates, and likely artifacts. Unmatched candidates need human inspection, repeated-frame evidence, and geometry checks before any discovery claim. The supplied status records surface geometry for 42 of the 106 prioritized rows; 64 rays have no surface intersection and are left without invented coordinates.
The training-readiness record contains zero accepted human labels. A review interface and an unlabeled queue do not constitute a trained model or a completed scientific validation campaign.
Learned models are future work
There is no trained CNN, YOLO, R-CNN, or reinforcement-learning system in this recorded detector. A learned model would require accepted positive/negative labels, a frozen benchmark, versioned training data, and comparison against this classical baseline.
Reproducibility
The supplied archive includes source code, scientific inputs, manifests, detector/model-status notes, validation reports, and review schemas. The published figures below summarize those artifacts; they do not substitute candidate volume for confirmed events.
Code & methodology
Read the source
Technical records.
About the evidence
Algorithm and Model Status; Current Results Summary dated July 2, 2026; detector model card, training-readiness report, and curated validation figures. Results describe the recorded snapshot.
Continue exploring.
← Back to Selected Builds